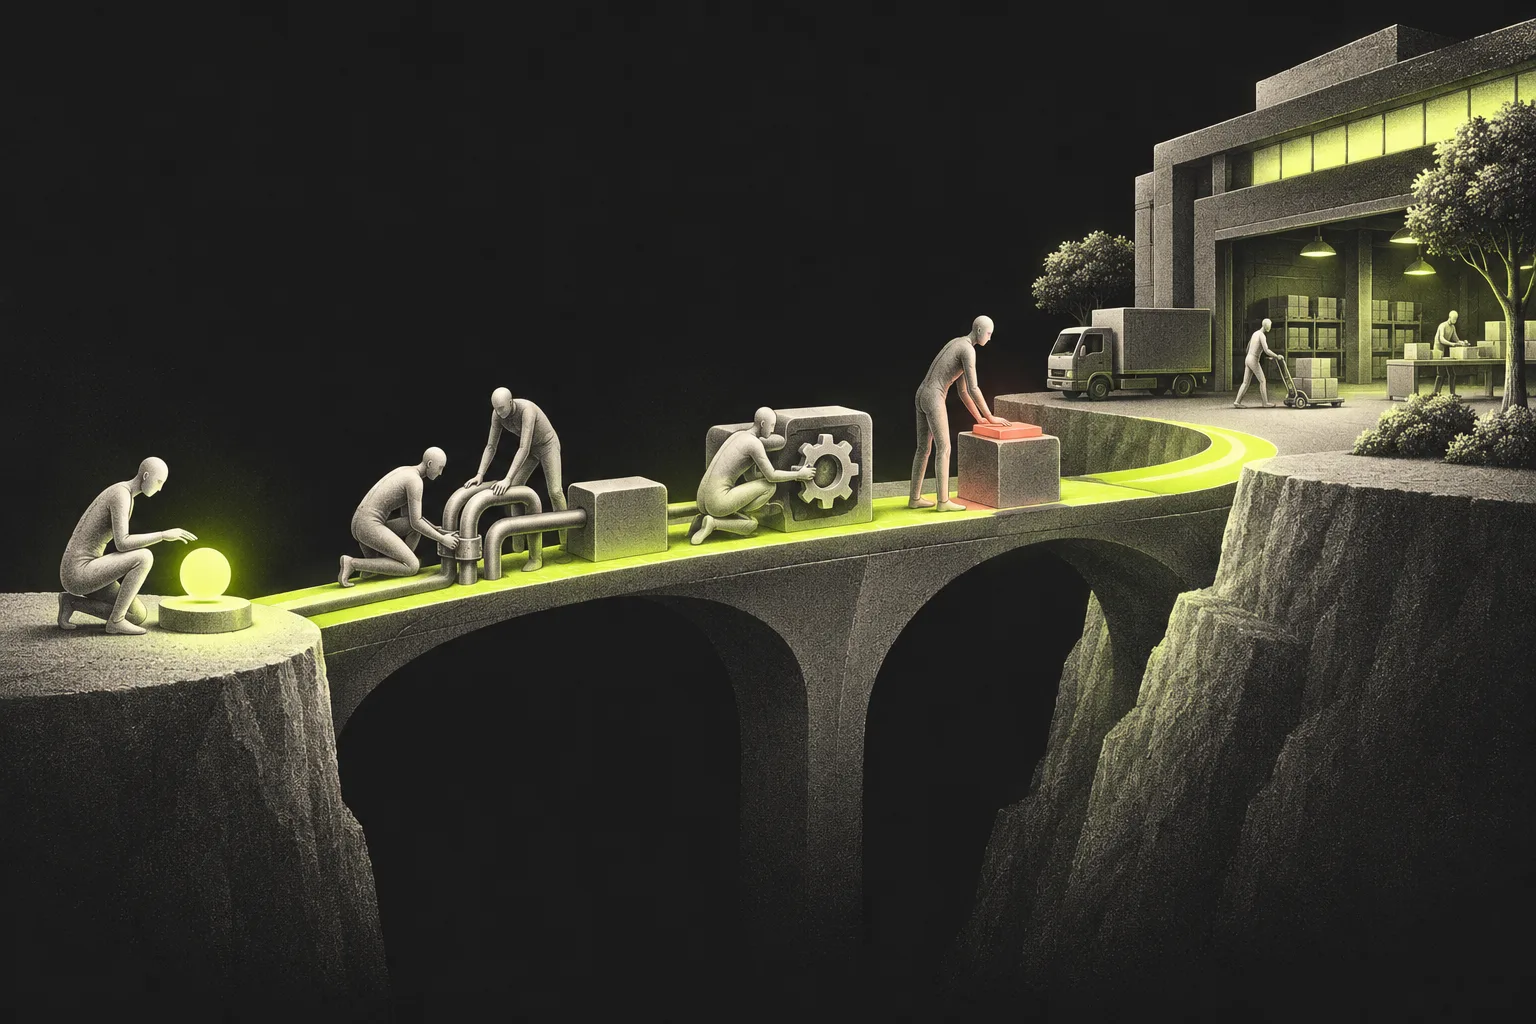
The demo takes four minutes. The agent reads the form, writes the email, updates the CRM, and books the meeting. Everyone in the room nods. Nobody asks the only question that matters: is this running anywhere on an ordinary Tuesday, when nobody is watching?
The production gap is the distance between systems that can be shown and systems that can be left running. Almost everyone in the market is on the demo side of it. The few on the other side are not easier to buy; they are easier to verify. That asymmetry is where credibility is earned, and where careful buyers should spend their attention.
How big is the production gap in 2026?
The honest answer: nobody agrees, because nobody agrees on what "in production" means. Read the demand side first. CrewAI's 2026 survey of 500 senior executives at organizations above 100 million dollars in revenue found every one of them planning to expand agentic AI, and 74 percent calling production deployment a critical or strategic priority. Those companies reported automating 31 percent of workflows on average, with another third expected in 2026. CrewAI sells agent platforms, so treat those numbers as a vendor describing the market it profits from.
The supply side splits on definitions. One roundup of Gartner's 2026 CIO survey puts enterprises with any agent in production at 17 percent. Mayfield's executive survey, as summarized by secondary coverage, reports 42 percent. The spread is definitional, and the definition matters more than the number. An employee using AI when they feel like it is not an agent doing a job end to end, unprompted, inside live operations. Surveys that blur that line produce numbers that flatter everyone and inform no one.
One figure cuts through both sides. IDC's finding, cited in Futurum's 2026 survey write-up, is that 88 percent of proofs of concept never reach wide deployment. Whatever the true production percentage is, the graveyard of pilots is larger.
Four questions separate deployment from demonstration
Ask anyone selling agentic AI for four things:
- The live system, not a slide of it. A screen share of the running deployment, with real data flowing.
- The task it completes without a human prompt. Not "the human types a request." The trigger, the schedule, the event that starts the work on its own.
- The metric it moved, with a before and after. Response time, meetings booked, renewals flagged. One number, two dates.
- What happens when it fails. Every system fails somewhere. A deployed one has an answer: it retries, it escalates, it stops by policy.
A demo answers none of these. A deployment answers all four, and the answers cost the seller nothing to give, because they are the operating record. The odds favor the demo anyway: that IDC figure above exists precisely because showing is cheap and running is not.
Why the gap persists
Running is not harder because the technology is weak. Running is harder because live operations contain everything a demo politely excludes: malformed form submissions, CRM records with three owners, a customer who replies in a language the brief did not anticipate, an API that rate-limits on the busiest day of the month. A demo optimizes the happy path. A deployment has to survive every path, which means policies for failure, checks on output, and a person on call for the cases that were nobody's favorite.
This is also why the gap is an opportunity and not a scandal. The work of closing it, the integrations, the guardrails, the evaluation runs against real past cases, is exactly the work that compounds into an operating track record. Anyone can borrow a demo. Nobody can borrow a year of logs.
What this is not
This is not an argument that demos are worthless. A good demo shows fit: whether the system understands your domain's vocabulary and shape of work. Watch it. Then refuse to let it be the evidence.
It is also not a claim that every use case deserves end-to-end autonomy. Plenty of valuable deployments keep a human in the loop by design, with the agent doing ninety percent and escalating the rest. The test is not whether a human is involved; it is whether the involvement was designed or accidental.
The move
Before your next agentic AI meeting, send the four questions ahead and ask for written answers. The reply itself is diagnostic. A vendor with a deployment attaches two links and a number. A vendor with a demo attaches a deck, and now you know in advance what the meeting was going to be.
Then, if the answers hold, run a two-week live pilot in one corner of the operation with real volume, real tools, and a kill switch. Inspect the logs yourself. Two weeks of logs teach more than two quarters of slide decks.
Take-home
- Write the four questions into your standard evaluation template today, so the next conversation starts past the demo.
- Ask your current AI vendors which of their features run unprompted in production for you. The gap inside your own stack is usually instructive.
- For one workflow you are considering, request the failure story first: what broke last month, and what changed because of it.
FAQ
Is a demo worthless, then?
No. It demonstrates fit and imagination, both useful. It demonstrates nothing about reliability, which is the property you are actually buying. Treat the demo as a first date and the four questions as a background check.
How long should a real deployment take?
A first working system on one workflow usually goes live in weeks, not quarters, but the honest answer depends on integrations and data quality more than on the vendor. Suspicion should flow toward timelines that promise production maturity in days.
What is the most common failure mode after go-live?
Unreviewed output at scale. The system runs, the volume arrives, and nobody budgeted for verification. The review layer, not the model, is where deployments stall, as argued in [the review bottleneck](/insights/the-review-bottleneck-is-the-real-cost-center-in-ai-teams).
Does the 88 percent PoC failure figure mean pilots are bad?
It means pilots that end are the norm, and that is not entirely bad. A pilot should convert into a deployment, a redesign, or a stop. The failure is the pilot designed to never decide anything.